OpenAI's own production agent framework, built around three primitives: Agent, Runner, and function_tool. The same primitives power AgentKit's visual builder underneath — so skills you learn in code transfer when you later compose flows in a UI.
Think of the SDK as opinionated glue: you describe who the agent is (instructions + model), what it can do (tools and optional handoff targets), and the Runner owns the loop — call the model, execute requested tools, feed results back, repeat until the model returns a final answer or hits a guardrail.
Core concepts
- Agent & Runner: An
Agentholds the model, system instructions, tools, and optionalhandoffsto other agents. You never manually alternate “model → tool → model” in application code — you pass the user message toRunner.run_sync()orawait Runner.run(), and the runner executes the full tool-calling loop with consistent error handling. This is the mental model most other Python agent frameworks copy, but OpenAI's version is tightly integrated with OpenAI models, tracing, and hosted tools. Agents SDK Docs · Read more: OpenAI Agents guide @function_tooldecorator: Turns a plain Python function into a callable tool by reading its type hints and docstring — no separate JSON schema file to keep in sync. The model sees a structured tool definition derived from your function signature; when it “calls” the tool, the SDK invokes your Python code and returns the result to the model. Good docstrings on parameters directly improve tool-selection accuracy.- Handoffs: Agents can delegate the conversation to a specialized sub-agent via
handoffs=[]— for example, a triage agent that routes billing vs. technical questions without stuffing every tool into one prompt. Handoffs are OpenAI's built-in answer to multi-agent systems while staying in one SDK (compare to explicit supervisor graphs in LangGraph). - Guardrails: Built-in input/output guardrails can halt a run before an unsafe or off-policy action executes — useful when agents have write access (send email, charge card, delete data). Treat guardrails as product requirements, not an afterthought.
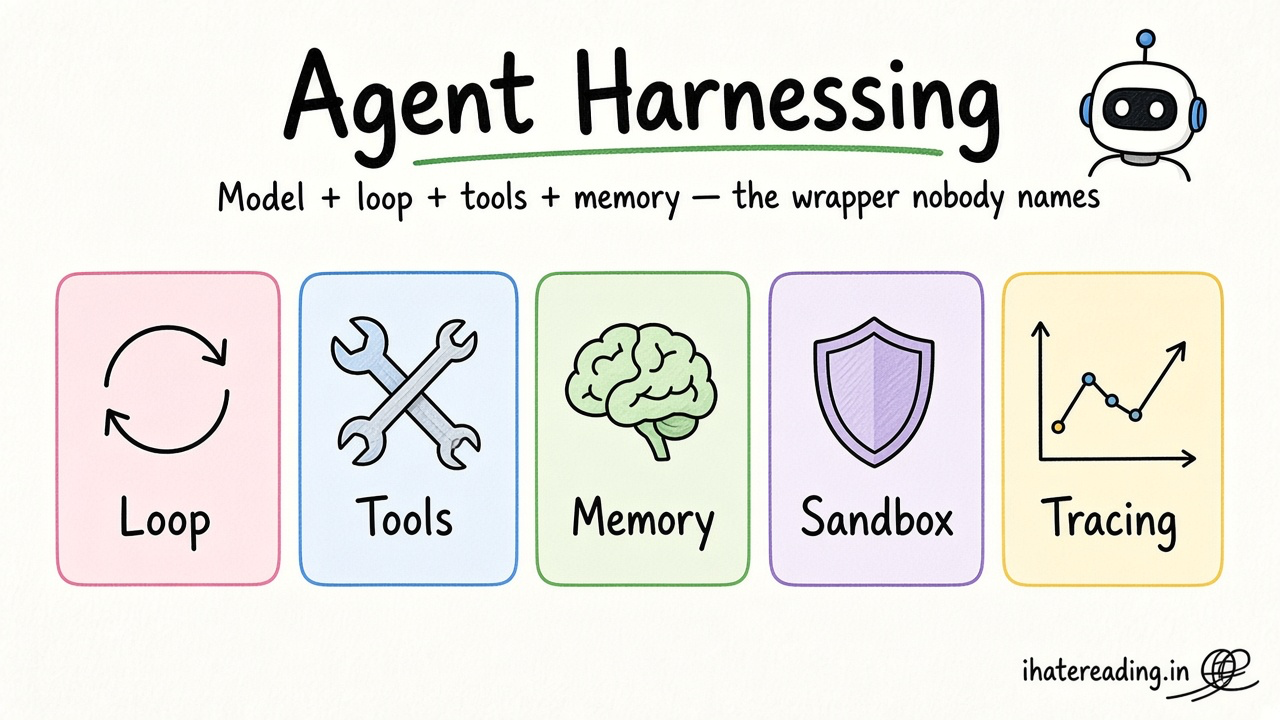
- Tracing: Every model call, tool call, and handoff is automatically recorded and viewable in a tracing dashboard — no manual OpenTelemetry wiring for the default path. Use traces to debug “why did it call that tool?” and to build eval datasets from production failures.
- Sessions & context: Multi-turn agents need explicit session or memory strategy — the SDK can carry conversation state across turns; pair with your own compaction or vector memory when threads get long (see the Memory chapter in this roadmap).
- When to pick this SDK: Best default if you are on OpenAI models, want minimal boilerplate for tool loops, and plan to use OpenAI-hosted tooling (file search, web, etc.) or AgentKit later. For strict typed outputs as first-class citizens, also evaluate Pydantic-AI; for graph-shaped control flow, see LangGraph.
Why it matters
If you already use OpenAI, this is the shortest route to a tool loop with tracing and handoffs, and the SDK follows the platform as it changes.
Where people get stuck
- Putting all the business logic in giant instructions. Use tools and code for the deterministic steps and keep prompts for judgment.
- No handling for tool timeouts. Runner loops need retries and a failure the user can see.
- Skipping tracing because the demo is short. You can't debug a multi-tool failure without spans.
Try this
Build one function_tool that returns structured JSON and log every Runner step locally.
Interview question
What are the three core primitives of the OpenAI Agents SDK?
Agent (model and instructions), Runner (the execution loop) and function_tool (a typed tool binding).
Resources
YouTube learning
Core concepts from video walkthroughs: