Shipping an agent isn't the finish line — knowing whether it's actually working, and proving that to a regulator or an enterprise buyer, increasingly is.
Tracing answers “what happened on this run?” (model calls, tools, latency, cost). Compliance answers “can we defend this system to legal and security?” — audit trails, misalignment, and regulatory expectations. You need both before calling an agent production-ready.
What Is It?
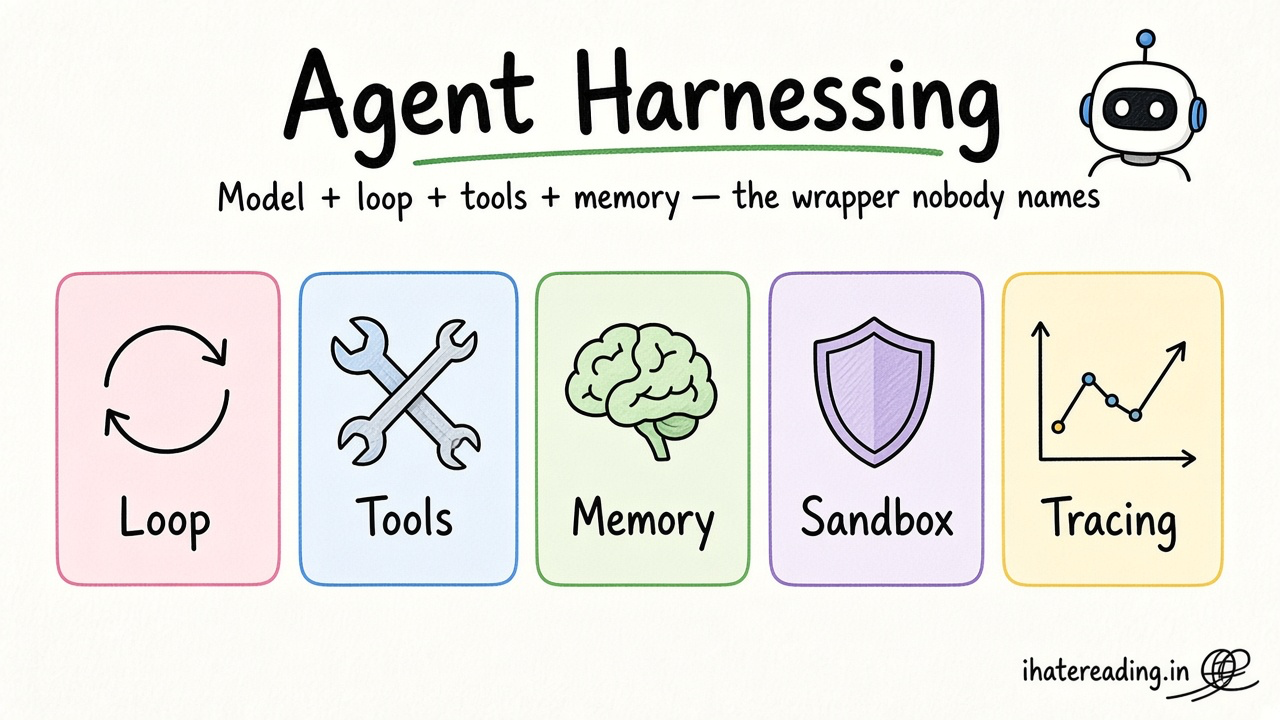
Observability for agents includes traces across tool calls, eval suites, and compliance logs.
Distinct from generic LLM logging — multi-step causality matters.
Child pages cover Langfuse/LangSmith/Braintrust and regulatory alignment.
Why Should I Care?
Agents fail in chains — you need span-level visibility.
Regulated industries ask for audit trails beyond accuracy metrics.
Real World Analogy
Observability is the black box flight recorder — when the agent loops or lies, you replay the tape instead of guessing.
Visual Mental Model
traces + evals + compliance auditsBeginner Explanation
Shipping is not the finish line. This hub covers tracing/evals and compliance auditing — know if the agent works and prove it to others.
Smallest Possible Example
trace = {"step": "tool_call", "latency_ms": 120}
print(trace)
Common Mistakes
❌ Logging only final assistant text.
You lose tool inputs/outputs needed to debug.
❌ No eval regression on prompt changes.
Silent quality cliffs after 'small' tweaks.
❌ Storing PII in traces without retention policy.
Compliance violations and security risk.
Real Project Example
LangSmith and Langfuse back many LangChain-style production deployments.
Braintrust popular for eval-driven agent iteration in startups.
Build This Mini Project
Add structured log lines for each tool call in a toy agent (name, latency, success). Review what you'd need for a trace UI.
Interview Question
How is agent observability different from app logging?
You must correlate multi-step LLM, tool, and retrieval spans with inputs/outputs per step, plus run eval datasets — not just HTTP status codes.
Key Takeaways
- Hub splits tracing vs compliance.
- Trace every tool hop.
- Eval prompts like code changes.
- Govern PII in logs.
YouTube learning
Core concepts from video walkthroughs: