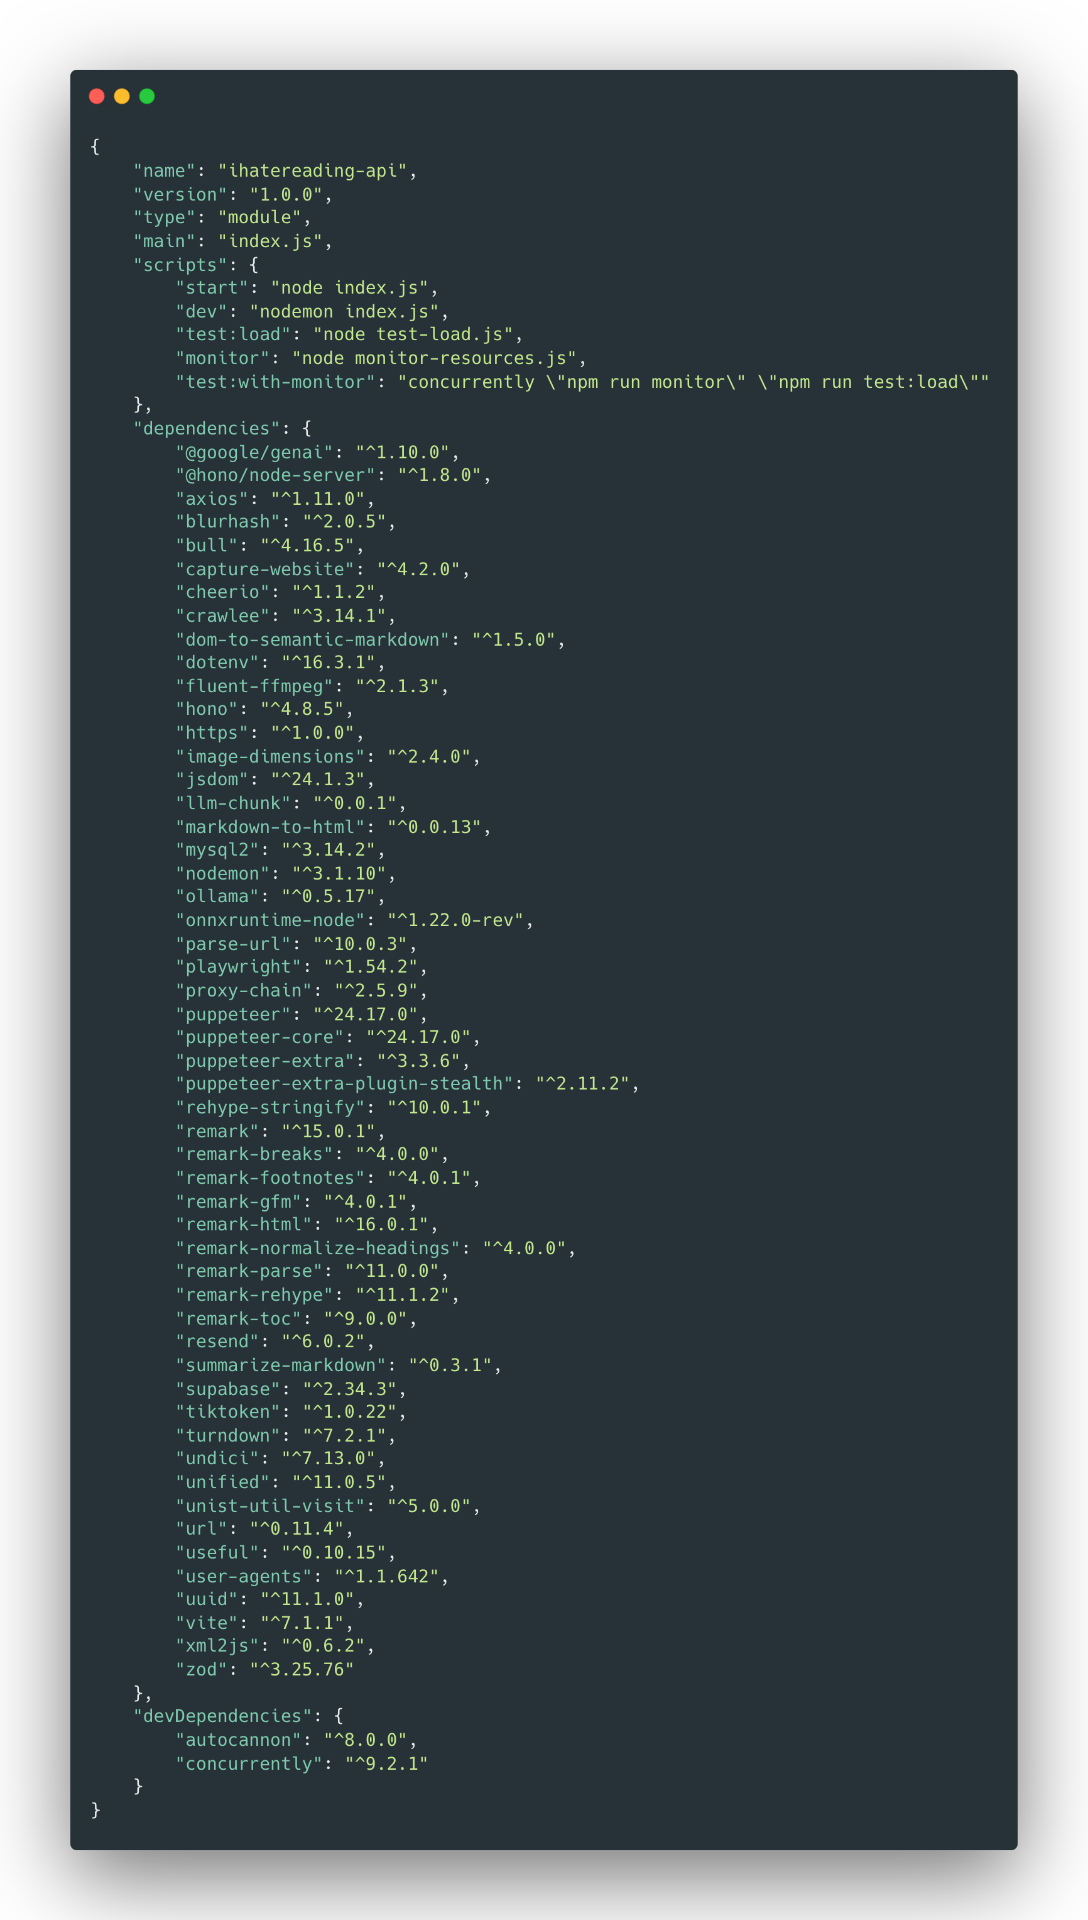
The art of finding new npm packages is no longer an art because one can curiously keep asking questions to LLM or GPT to quench their curiosity
But still reading github repository along with finding new packages in package.json is the best art to know the exact usecase and implementation simultaenously.
I've started paying attention to github source code for any app in the world, if open-source whereas earlier I use to check the website and apply fundamental first principle thinking to lay down the execution steps for any product in the world.
This technique still works but didn't give you complete understanding so slowly but steadily I started reading github souce code a lot. Recently I was checking Firecrawl website, and those who have used Perplexity and chatGPT can understand that scraping content from URLs and the internet and passing it down to LLM model to answer better and up-to-date is the best alternative to Google search, in fact, the best way to kill Google Search.
Never mind, coming back to the important point, scraping content have 2 purposes
- Scrape the entire internet store data to train machine learning or LLM models
- Scrape content to pass to the LLM model for better answering and context
In our case, we will be following the second option, scraping content from the internet to use as a context for the LLM model for better answering with the latest information.
When I started digging deep into Firecrawl implementation on github source code, I found a few more unknown packages, which I'll be discussing today
Undici: the npm module alternative to fetch, axios, mainly for XMLHTTP request
Quite fast, then fetch, and mainly used to make HTTP requests
I was shocked that devs are using undici over axios and fetch, one can read more on chatgpt about the same.
See I really don't believe in answering all your doubts or questions; instead, I leave the topic/doubt/question to your curiosity to reach the answer.
Moving ahead with semantic-html-markdown
Next, we have some npm modules to transpile and convert the markdown into HTML and vice versa, because we scrape a lot of content from the internet, as it returns HTML, so we need some modules to convert it into markdown.
The above packages will certainly help to convert content from Markdown to HTML and vice versa.
Moving ahead with proxy-related packages that help to rotate IPS and proxies while scraping content from the internet. Rotating IPs is important to avoid getting blocked.
Then we have a few known packages for scraping, as given below
A few more packages I've found that are mind-blowing, but didn't get much attention
Let's keep the story short, see you in the next one
Shrey